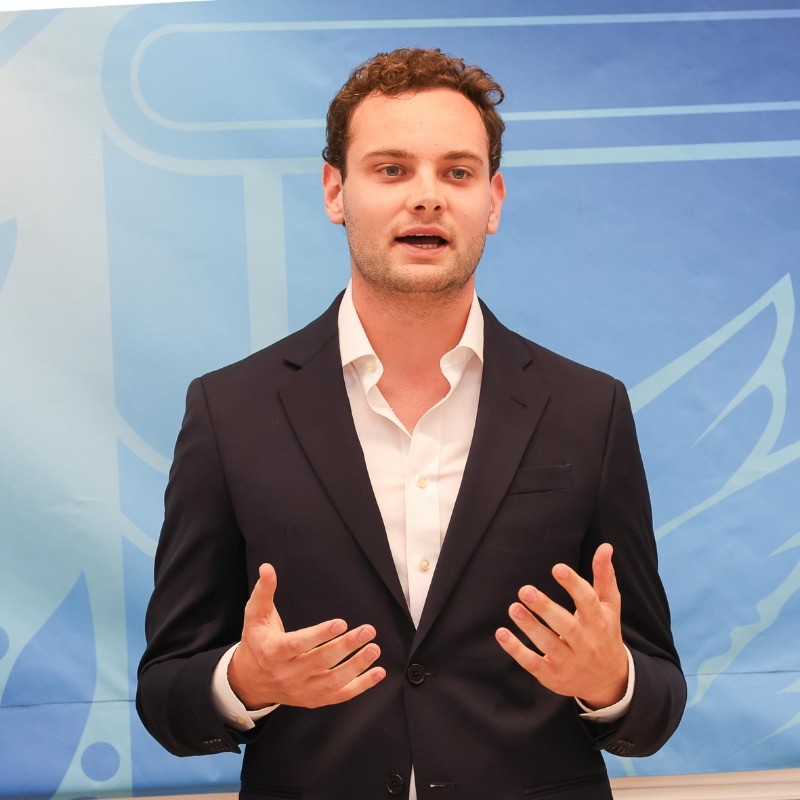
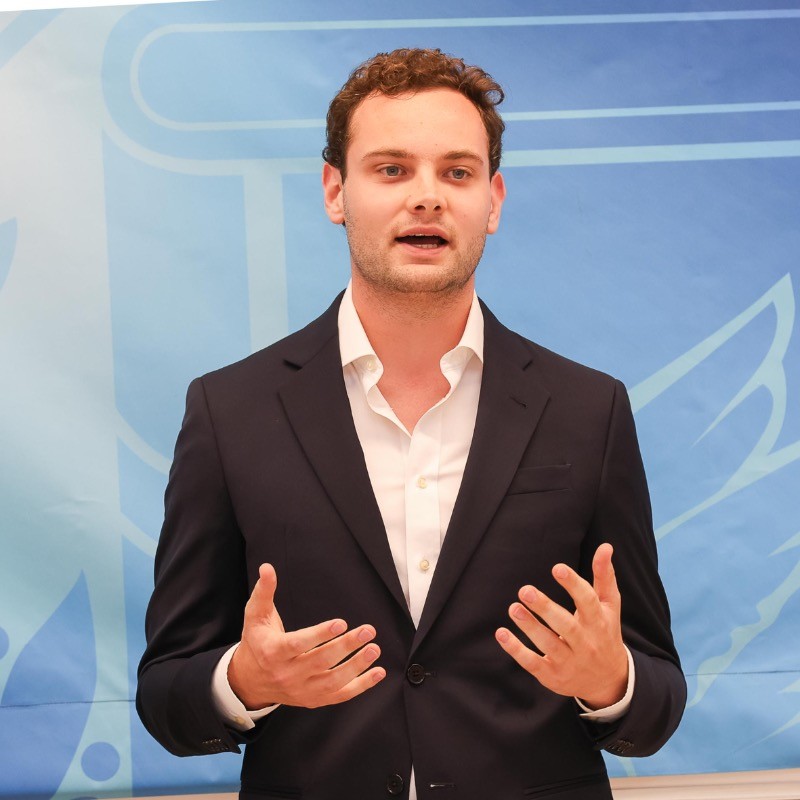
Ian Ronk
Ian Ronk
Head of Data
Amsterdam, NL

From
client question
to production system.

I am Ian. I build and run production data systems for pension funds, real estate investors and national statistical offices. I take an open client question, turn it into a method and ship the system that answers it.
Focus areasData EngineeringSystem ArchitectureClient & Stakeholder WorkAnalytics & ML

Hi, I'm Ian.
I answer questions using data

I work as Head of Data: I lead the data team I built up to four engineers and own the data function end to end, from building and maintaining the data systems to collecting, processing and structuring data for products used by pension funds, national statistical offices and real estate investors, including a fund with €10B AuM.

The other half of the job is client-facing: I own the client relationships with pension funds, real estate investors and national statistical offices, present methodology to portfolio managers and defend it in reviews with Eurostat and CBS statisticians, and turn open client questions into systems we can build.

Read the full bio
Ian Ronk
RoleHead of Data
BasedAmsterdam, NL
EducationMSc Bocconi · BSc AI, UvA
StackBash · Python · PostGIS/SQL · Airflow · Iceberg

Focus Areas

Head of Data in practice: building the data infrastructure, setting up the systems underneath, owning the client side and running the analytics on top.

§ 03.01

Data Engineering

Building and maintaining data pipelines and efficient storage, such as three years of weekly collection/scraping across 8 different sources for a real estate fund with €10B AuM and then structuring, cleaning and deduplicating this data automatically.

AirflowPythonETLMonitoringIceberg
§ 03.02

System Architecture

Setting up the platform underneath: server instances, PostGIS, distributed Iceberg compute and data processing servers, networking/VPN, APIs and security. Example: 8 distributed servers run as the standing production infrastructure to handle loads of complex data products.

Linux/BashResource Management & S3Networking & APIsDockerDistributed Compute
§ 03.03

Client & Stakeholder Work

The client side of the job: methodology reviews with Eurostat and CBS statisticians, presentations to portfolio managers, and long-run client relationships with pension funds, real estate investors and national statistical offices. Open questions come in; production APIs go out.

Methodology reviewsPresentationsRequirement definitionOCRData Validation
§ 03.04

Analytics & ML

The analysis layer on top: nowcasting, ABM simulations, regressions, statistical methods and applied ML that ships: from hedonic price models, to image classification to statistically sound time series analyses.

RegressionTime SeriesSimulationsNowcastingStatistical Analysis

Projects & papers.

Eight pieces of work across the four lanes: production systems, shipped products, and the research they make possible.

t=0t=10yattractiveness ↑affordability ↓parcels: AMS · UTRECHT · MILAN
§ 04.03MSc Thesis · BocconiRESEARCH

Gentrification agent-based model

My MSc Thesis research on gentrification, where I built an agent-based model of neighbourhood change: households interact with neighborhoods in the treated cities Amsterdam, Utrecht and Milan based on their own income, the affordability of the neighborhood and the attractiveness, based on elements such as streetview imagery 'beauty' classification, GTFS connectivity, greenery and neighborhood sentiment online. A two-tenure social-housing extension is in progress.

Python/GeoPandasLarge Vision ModelPostGISAgent-based Modeling
DAGingest726 GBguardtransformqueuecelery workers
§ 04.04EngineeringPROJECT

Research pipelines as production systems

My research projects run on Airflow 3 data pipelines that are hosted in this project. It can scale from a laptop to a multi-machine CeleryExecutor cluster. This project was built with idempotency guards, custom operators and agentic monitoring.

AirflowCeleryDockerCIDuckDB
conversationlemmatizeSM-21d6d15dnext-day6,200 vocab · A1–C1
§ 04.05AI productPROJECT

LanguageBuddy: AI language tutor

A self-hosted AI language tutor for Dutch, Italian and Spanish, built on language learning research that includes a chat or voice-call LLM tutor and SM-2 repetition. Every mistake is captured into a spaced-repetition queue that drives the next day's exercises and uses a real-news scraper for reading learning. Follows the CEFR framework with 6,200+ vocabulary entries.

FastAPILLMTTSSQLiteDocker
p(sponsor)86% F10.54:326:05sentence-T5 → BiLSTM · 38,600 videos
§ 04.06NLP · sequence taggingPROJECT

SponsoredBye: sponsor-segment detection

A text-only sponsor-skipper for YouTube: sentence-T5 embeddings feed a BiLSTM sequence tagger that flags sponsored sentences and maps them back to timestamps, cutting segmentation error to 16% WindowDiff against a 99% naive baseline.

TensorFlowBiLSTMsentence-T5MongoDBHuggingface
SAM224pxResNet501/638.8 MB on-device
§ 04.07Mobile MLPROJECT

FishFinder: photo-to-species ID

A Flutter app that identifies 63 Dutch fish species from a photo, fully on-device, and fills a Pokédex-style FishDex as you catch them. The training pipeline: ~3,000 hand-annotated photos masked with Segment Anything Model, then a fine-tuned ResNet50 (a 90 MB full model) compressed to an 8.8 MB TFLite model for on-device use.

Flutter/DartTFLiteResNet50Segment Anything Model (SAM)Firebase
RF 97%33 featuresd(river)Δhimperv. 500m–5kmw.l.
§ 04.08BSc Thesis · UvARESEARCH

Predicting flooding risk from local features

My BSc thesis, looking at whether flood risk can be explained by local features instead of a black-box hydrodynamic simulation. Collected 33 features across ~45,000 European locations, such as ground imperviousness, ground type and distance to river, across 100GB+ of data and ran a Random Forest to find their relation. Findings: 97% on the binary 20-year flood question, with surrounding imperviousness and relative height doing most of the work.

scikit-learnRandom Forestraster dataGIS

Papers.

Methods, data and results behind the projects. All papers →

01
2026-08-14
Calibrating Free Postcode Boundaries from OpenStreetMap: A Transferable Seed-Density Accuracy CurvePostcode boundary polygons are unavailable free of charge for much of Europe: some countries publish authoritative layers, elsewhere they are sold or absent. Voronoi tessellation of OpenStreetMap address points is the natural estimator, but how many address points are needed, and whether the answer transfers across countries, has not been established. We calibrate a single OSM-Voronoi pipeline against national references in the Netherlands and Denmark (5,160 reference polygons), fit a seed-density-to-IoU curve, and test out-of-sample transfer to held-out Belgium (1,188 polygons). The asymptote is robust across functional forms (mean matched IoU saturates at 0.76–0.82), while the fitted 0.7-IoU threshold is form-sensitive (roughly 40–110 seeds); per-postcode scatter is wide (point-level R² of about 0.26), so the curve calibrates the population mean, not individual polygons. Belgium reaches mean matched IoU 0.618 at 81% coverage, near the curve. Applied to Italy, where no free authoritative intra-city postcode layer exists, the pipeline produces 4,209 estimated CAP polygons; Milan reaches mean IoU 0.783 against the community uMap reference (an earlier pipeline configuration), and the 2,903 matched single-CAP municipalities at median 19 seeds land where the curve predicts (mean IoU 0.500). A Swiss evaluation, where the asymptote falls to 0.644, marks the boundary of the regime.
WORKING-PAPER
02
2026-07-09
When Does Metro Infrastructure Capitalize into Property Prices? Phase-Decomposed Difference-in-Differences Evidence from Seven European CitiesWe study when, not merely whether, new metro lines capitalize into residential property prices. Seventeen staggered treated cohorts across seven European cities in five countries (Milano, Amsterdam, Copenhagen, Paris, Helsinki, Rennes, Roma) pool into a single phase-decomposed panel (n = 42,004), with the response decomposed into announcement, construction, opening, and maturity phases. The pooled cross-city average locates the largest response at maturity: prices step up by +9 to +12% (drop-Roma to full-sample, measured as the construction-to-maturity contrast) two or more years after opening, a step that is stable across the control ladder and positive under every leave-one-city-out. The step is a pooled average, however, not a within-city fact. City-by-year fixed effects collapse it to an insignificant -0.5 log points while leaving a +2.5 log-point step at opening, a within-city contrast that is itself entity-clustered ordering evidence, not significant under city-clustered bootstrap. Few-cluster significance of the maturity step is partition- and control-set-dependent: a restricted wild cluster bootstrap gives p = 0.036 clustered on the seven cities (level-only controls; p = 0.080 with the full control set) but p = 0.16 on the twenty-four cohorts. Roma, priced through the same OMI appraisal series as Milano, is itself a within-city null whose pooled contribution runs entirely through the common-year fixed effects, and it disciplines the upper-bound reading throughout. The defensible magnitudes are per-city: foremost Milano's within-ring +167 EUR/m² (≈ +5.6%, wild-bootstrap p = 0.004). We read the delayed-to-maturity step as a cross-city pattern worth testing on longer panels, not as a settled within-city effect.
IN PROGRESS
03
2025-03-05
US vs EU: does training-data geography matter for autonomous-driving object detection?Does an object detector trained on US dashcam data still work on European streets? An original 2024 course project suggested catastrophic transfer failure, but was confounded: precision-only metrics, no held-out test set, a resolution mismatch between datasets, and models never trained in-domain. This controlled redo runs a 2×3 design ({zero-shot COCO, US-fine-tuned, EU-fine-tuned} × {US-test, EU-test}) with YOLOv3u and YOLOv8s on Udacity/CrowdAI (US) and KITTI (EU). On EU test data, EU fine-tuning gains +0.153 mAP@0.5:0.95 over zero-shot while US fine-tuning gains +0.001; the difference-in-differences gap is +0.077 ± 0.007 across three seeds. The pattern is mirror-symmetric, so the correct read is narrow fine-tune specialisation rather than a US-specific geographic bias, with one asymmetry that is genuinely geographic: bicycle detection collapses without European training data.
WORKING-PAPER

Questions, ideas, roles? Get in touch.

ContactGitHub
Ian Ronk | Head of Data: data systems, analytics, and urban-dynamics research